
Image: Pexels, used under the Pexels License.
Meta told reporters on October 17 that it had taken the word "train" out of the crawling clause in its new Commercial Terms. Its own preview pages now agree. On October 19 the UK English edition, the one Facebook served us by default, still had the original sentence; when we reloaded both editions on October 22, the UK page carried the same narrower wording as the US page.
The narrower wording hasn't settled anything. The UK's Competition and Markets Authority has written to Meta, and two German publisher associations have asked the European Commission to stop the clause before it applies. If you run a business on Facebook, Instagram or Meta ads, you still can't opt out: the terms say continued business use after notice means you agree. Here's what the clause says now, who's pushing back, who it covers and what you can do before the effective date.
Event date: October 17, 2026 (Meta revised the crawling clause after criticism). First reports: October 17, 2026, by The Verge and Nieman Lab; TechCrunch followed the same evening. Updated October 22, 2026: the CMA's letter and the German publishers' request (both made public October 20), and our recheck of both editions.
What Meta changed
The story started with Nieman Lab on October 15, where legal experts read the new clause as letting Meta scrape any website "associated with" a business account and use the content to train its AI. Andy Stone, Meta's vice president of communications, called that reading false the next day.
https://x.com/andymstone/status/2111101865769201850
On October 17 Meta revised the text. According to Nieman Lab's follow-up, the company removed "train" from the list of allowed uses and limited those uses to "advertising and business products." A Meta spokesperson told The Verge: "We've heard you and want to clarify: the crawling terms we consolidated only applied to our ads and business products, and we've clarified that in the terms themselves."
A day later, PPC Land reported that the UK English preview it captured on October 18 still held the old sentence, and we saw the same on October 19. By October 22 that had changed. We loaded Meta's preview page in both English editions that morning (UTC): the crawl paragraph reads the same in each apart from spelling, and neither contains the word train.
| Edition of the preview | What Meta may do with crawled content | Says "train"? | Checked |
|---|---|---|---|
| English (US) | "provide, develop, improve, research, and maintain advertising and business products" and "maintain the integrity and security of Meta Company Products" | No | Oct 22, 2026 |
| English (UK), shown by default | "provide, develop, improve, research and maintain advertising and business products" and "maintain the integrity and security of Meta Company Products" | No (it did on Oct 19) | Oct 22, 2026 |
| Both | Crawl any domain "associated with your products or services," using "test credentials" if needed; neither mentions robots.txt | n/a | Oct 22, 2026 |
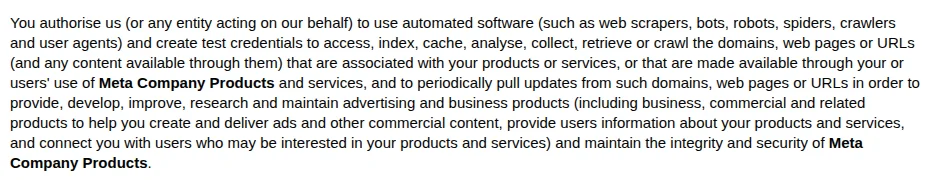
Screenshot: Meta Commercial Terms preview, English (UK) edition, Meta. Captured October 22, 2026.
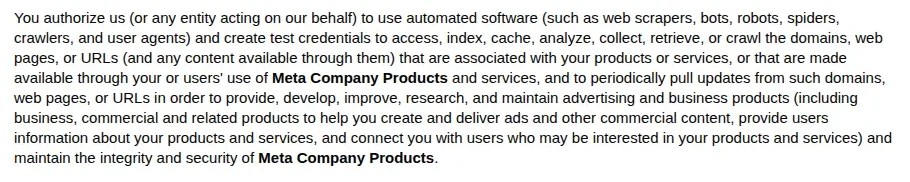
Screenshot: Meta Commercial Terms preview, English (US) edition, Meta. Captured October 19, 2026.
The CMA and German publishers want it stopped
On October 20 the House of Lords Communications and Digital Committee took evidence from the CMA: Sarah Cardell, its chief executive, and Will Hayter, executive director for digital markets. Baroness Fleet, a former Evening Standard editor, pressed them on Meta's terms. "We wrote them a letter yesterday to ask them for information on it, and I'm actually talking to them tomorrow to make sure we've understood what's going on, and then we'll work out what to do next," Hayter said, as Press Gazette reported.
Cardell was plain about the limits: "We obviously don't have a live designation in relation to Meta. There is the option also of using our competition enforcement powers." Without that designation, Press Gazette notes, the CMA can't take formal action to stop the change. Cardell said the authority would consider its next steps urgently once it understood Meta's position.
The same day, the German publisher associations BDZV and MVFP asked the European Commission to examine the change at once and prohibit its use until that review is finished. They argue the clause breaches Article 6(12) of the Digital Markets Act, which requires Meta, as gatekeeper for Facebook and Instagram, to give business users fair, reasonable and non-discriminatory access conditions, and that it is an abusive tie. In their reading, dropping "train" fixes nothing: grounding, retrieval-augmented generation, semantic search, summaries and recommendation systems are all still covered. Their name for the clause is "skrupelloser Diebstahl," unscrupulous theft.
The terms themselves point EU business users of Meta's social networks to its alternative dispute settlement mechanism under that same Article 6(12).
Who the terms cover
More businesses than the headlines suggest. The preview defines business or commercial purposes to include "using ads or marketing messages, selling or listing products, developing apps," "managing a Page," and "using any business product, such as Ads Manager or Meta Business Suite." A two-person shop with a Facebook Page counts.
The update clause does the rest. Continuing "any access or use of any Meta Company Products for business or commercial purposes after any notice of an update" means you're bound, and the only exit the text offers is this: "If you do not agree to the updated terms, you may stop all access or use of our Products for business or commercial purposes." If you or your business is in the US, both editions also send most disputes to binding arbitration on an individual basis, with no class actions or jury trials.
Even the narrower wording worries lawyers. "I think 'develop' is broad enough to include 'train,'" Matt Topic, a media and IP attorney at Loevy & Loevy, told Nieman Lab. James Grimmelmann of Cornell Law School said the "develop...advertising and business products" language is "still broad enough to drive a truck through."
What robots.txt does and doesn't do
Meta's spokesperson told Nieman Lab that content owners "still have the ability to disable the crawler via robots.txt flags." That promise sits in a press statement, not in the contract: the word robots.txt appears in neither edition.
Meta's web crawlers page is where the controls live. It names a crawler for each job, and two of them can ignore your file.
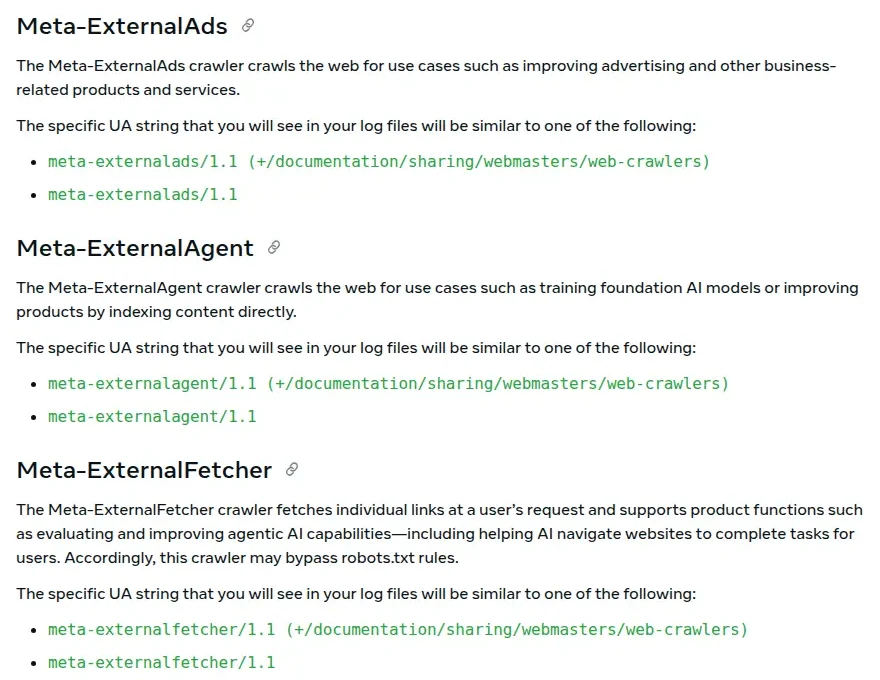
Screenshot: Meta web crawlers documentation, Meta for Developers. Captured October 19, 2026.
- Meta-ExternalAgent crawls "for use cases such as training foundation AI models or improving products by indexing content directly." This is the one to block if training is your concern.
- Meta-ExternalAds crawls "for use cases such as improving advertising and other business-related products and services," which matches the revised wording of the terms.
- Meta-ExternalFetcher "may bypass robots.txt rules" because it fetches links a user asked for, and FacebookExternalHit "might bypass robots.txt when performing security or integrity checks."
Meta says crawlers may cache robots.txt for up to 24 hours, so a change you make today takes about a day to bite. And a robots.txt rule is a request, not a right. Benjamin Sobel, a University of Wisconsin law professor, told Nieman Lab: "You can still express the preference, and unless it's a legally enforceable preference, it can still be ignored all the same."
What to do before the terms take effect
- Save a dated copy. Print the preview page to PDF with today's date, in each language edition your business uses (the language switcher is in the page footer). The UK English text changed between October 19 and October 22; if it changes again, you'll have what you agreed to.
- Block the training crawler. Add this to robots.txt on every domain linked from your Page, catalogue or ads:
User-agent: meta-externalagent
Disallow: /
- Think before blocking Meta-ExternalAds. Meta ties it to advertising products. If you rely on Meta ads or a product catalogue, test the change on one domain first; Meta's page doesn't say what blocking it does to ad delivery.
- Check your server logs for meta-externalagent, meta-externalads and meta-externalfetcher so you know what's already visiting.
- Flag the "test credentials" wording to whoever handles your paywall or member area. Grimmelmann told Nieman Lab it could technically let Meta sign up as a user to get past a registration wall, and Meta wouldn't say whether it would.
- Log it as a vendor change. Meta is now an AI vendor that sets its own terms by notice. Our AI vendor contract red flags list covers the same "continued use means consent" pattern.
What we could not confirm
Meta hasn't published a changelog for the October 17 revision, so we can't say exactly when the UK English page changed, only that it had by October 22. Neither edition says which language version controls. The committee's official transcript wasn't online when we checked on October 22, so the CMA quotes above are as Press Gazette reported them. The CMA hasn't said what came of its meeting with Meta, and we found no public response from the European Commission.
Our take
The revision is a real narrowing on paper, and both English editions now carry it. But the narrowing is smaller than it looks: "develop" still covers a lot, and the promise that matters most (robots.txt is respected) lives only in a press statement. The CMA and the German publishers may slow Meta down; don't plan around it. We'd save a dated copy, block Meta-ExternalAgent today, and treat the new terms the way we treat any AI vendor clause that changes by notice: assume the broadest reading until the text says otherwise.
Community reaction
On r/technology, the highest-voted reply to the Nieman Lab story was short: "Forced consent doesn't seem like consent," wrote u/Flashy_Worry7792. Not everyone agreed. "ok that has always been allowed this is such a non-story how do people think google search works??" replied u/Avimox, a comment the thread voted down.
Correction (October 22, 2026): An earlier version said the US English and UK English editions of Meta's preview disagree, and that the UK English edition still let Meta use crawled content to "train" Meta Company Products. That was the text we saw on October 19. When we rechecked on October 22, both editions limited crawled content to advertising and business products and neither said train; the title, table, screenshot, FAQ and first step were updated.
Related Reading
- AI Companies Built Empires by Scraping the Internet. Now They're Suing Anyone Who Scrapes Them Back.
- Does Your AI Vendor Train on Your Data? 7 Vendors Compared
- SPUR Coalition Adds NYT and Economist: What AI Builders Must Log
- USA Today Sues OpenAI: $250M Claim Over ChatGPT News Summaries
- Anthropic's $1.5B Copyright Settlement: Training Data Has a Price Now
- Amazon v. Perplexity: What the CFAA Ruling Means for AI Agents
- AI Vendor Contract Red Flags: 12 Clauses to Fix in 2026
- Meta Posed as Teenagers to Attack Rival AI Chatbots
